
Data quality is getting more attention than before. This is a result of a shift many organisations are seeing in their day‑to‑day operations: the focus has moved from AI experiments to operational processes. When data drives automation, AI solutions and operational decision‑making, quality becomes more than a reporting concern. Data quality becomes part of the overall reliability of the business.
In my own work, this often comes down to a very practical question: at which point can data quality actually be controlled, and how should it be done?
Let’s set aside the ideal scenario and look at reality. Data comes from legacy systems, CSV files, integrations, various sensors and manual processes, often with unclear ownership. In this environment, a central data team does its best but often ends up cleaning up after others.
This situation is familiar to many organisations. Work related to data quality tends to be fragmented and reactive. Issues are typically discovered only in reports, during morning checks, or when someone in the business asks why a number looks unusual.
This was already challenging in reporting. Now that data increasingly drives automation, AI solutions and operational decisions, the limitations of this operating model have become evident very quickly.
Independent research also supports the view that data quality is the result of many factors. Foidl et al. (2024) identified a total of 41 different factors affecting data pipeline quality, ranging from the data itself to integration and platform development, infrastructure, lifecycle management and data processing. From a practical perspective, this is familiar: quality does not emerge at a single checkpoint but from the combined effect of technical, organisational and process‑related factors. Similar conclusions are drawn in more recent research on data architecture, which emphasises integrating quality checks into the architecture itself rather than treating them as separate, after‑the‑fact controls (Abughazala et al., 2026).
It would be easy to say: fix governance. Yes, but how? Where should you start? Here’s one suggestion: data contracts.
The first controllable point in a data platform
Data quality often originates where the data is created: in business processes, source systems and frequently through manual input. Influencing this involves leadership, training, clear responsibilities, good guidance, effective processes and better systems.
This work is important.
It is also often slow.
From the perspective of a data platform, the first point that can truly be controlled is often when data arrives on the platform.
In simplified form, the process looks like this:
Source system / file / API → intake → staging / landing → transformation → curated data → reporting / AI / automation
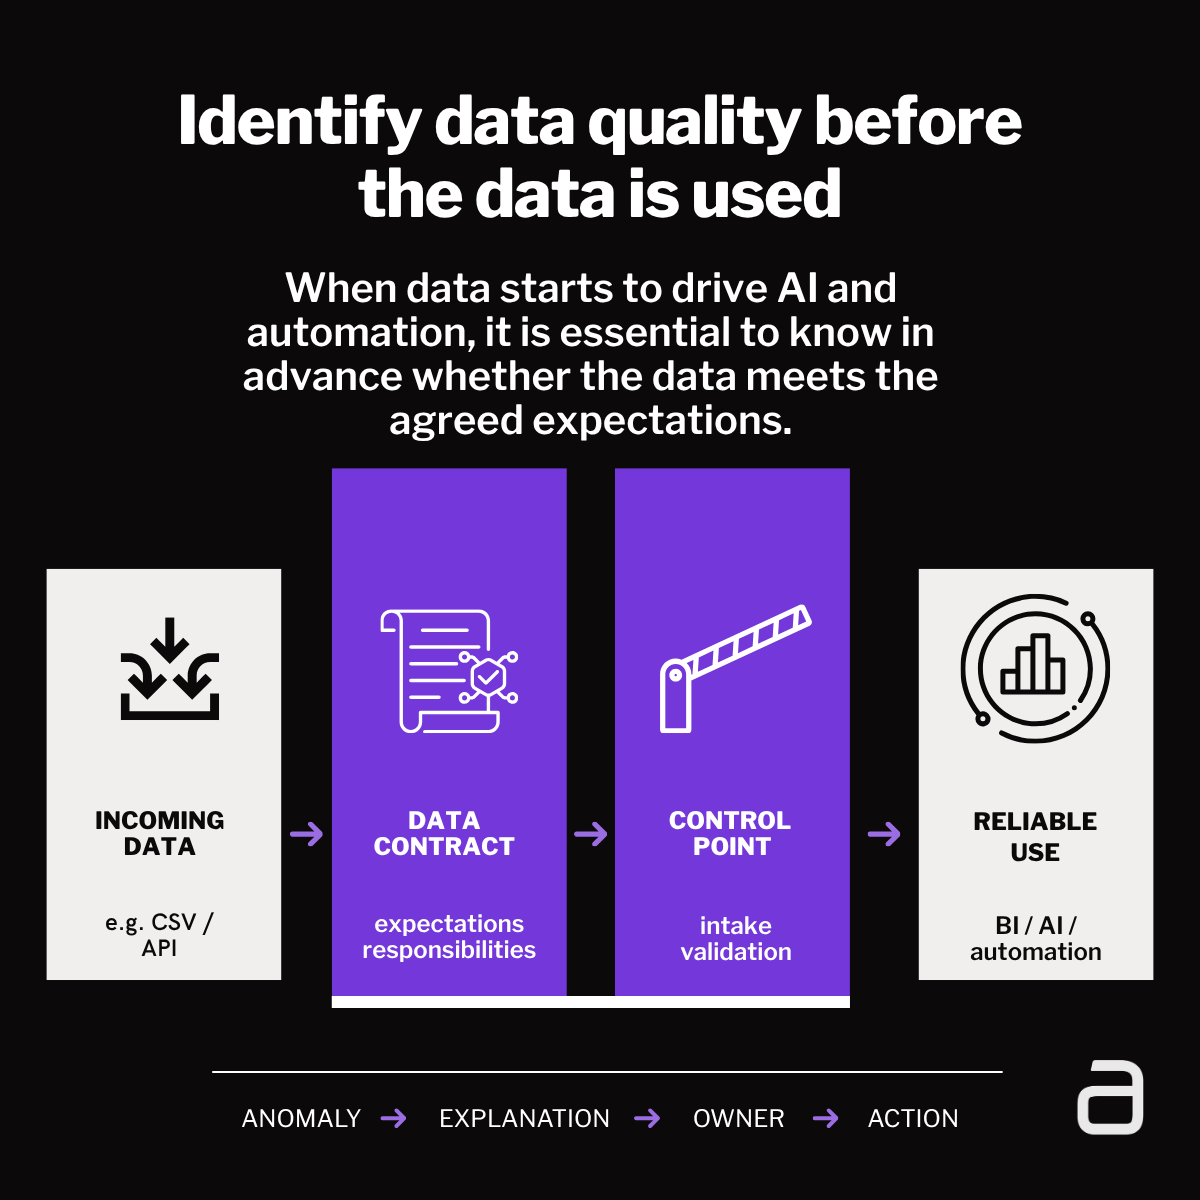
At the intake stage, it is possible to verify whether data has arrived at all, whether the volume matches expectations, whether the structure is as agreed and whether values appear plausible compared to historical data. This does not solve all data quality issues, but it creates a checkpoint for identifying anomalies before data flows further into reporting, automation or AI use.
This does not fix everything. Nor does it need to. The first task is to detect and explain.
If the number of rows in a file suddenly drops to a fraction of the usual level, that is information. If an email address appears in a numeric field, that is information. If a sales total deviates significantly from previous levels, that is also information.
The value comes from ensuring that this information does not remain just a technical error message but becomes a clear course of action: what happened, where it was detected, what it affects and who is responsible.
A data contract is more than a document
The concept of a data contract can sound like a technical or a legal concept. In this context, it is something very practical. For each important data flow, expectations are defined.
Where does the data come from? In what format? How often? Which fields are mandatory? What is the expected volume? Who owns the data? What happens if expectations are not met?
When this is defined in a machine‑readable format, for example as a version‑controlled YAML or JSON specification, it becomes more than documentation. It enables validation, testing, monitoring and incident handling. At the same time, it creates a shared language between data producers, integration teams, the data platform and the business.
This is where a significant shift happens in my opinion. Data quality is no longer solely the responsibility of the data team. Instead, it becomes part of an agreement about what data the organisation can rely on and under what conditions.
A good starting point
At this point, it is important to be honest. Data contracts will not solve all data quality challenges across the organisation. They will not fix source systems, create a perfect data model or automate all error correction. Nor do they replace a comprehensive data governance model.
A good first step is to select a few data flows with clear business relevance. Define data contracts for them, implement initial validation checks and agree on how exceptions are handled. This creates immediate, tangible value and avoids getting stuck in abstract governance plans. The result is a small but concrete control point that indicates early on whether the data can be trusted, one data flow at a time. The approach is also easy to scale once its effectiveness has been demonstrated.
AI can later assist in explaining anomalies, summarising impacts and even generating suggestions for corrective actions. But first, detection points are needed. Otherwise, AI ends up explaining an unclear situation based on unclear data.
Sources
Abughazala, M., Sharaf, M., & Muccini, H. (2026). Architecting data-intensive applications: From architectural design to data quality. Information and Software Technology, 196, 108156.
Foidl, H., Golendukhina, V., Ramler, R., & Felderer, M. (2024). Data pipeline quality: Influencing factors, root causes of data-related issues, and processing problem areas for developers. Journal of Systems and Software, 207, 111855.
About the author
Tuuli is Ambientia’s Director of Data and AI. She helps organisations bring data and artificial intelligence into practical business use. Her work focuses on the conditions that make data useful: clear problem definition, human-centered design, effective processes, and reliable, accessible data that can support decisions and automation. Tuuli also supports organizations in building and operationalizing data and AI governance models.
Tuuli has more than 25 years of experience in developing digital business across programming, customer experience, leadership, and business development. Her previous background as a Creative Director is reflected in her ability to connect technology, people, and business goals into understandable and practical wholes.

Subscribe to our content
Do you want our content in your email? Among other things, we offer information on service management and customer experience development
More related

Artikkelit
Data Quality in AI Initiatives – What Makes Data AI-Ready?
Explore the critical role of data quality in AI initiatives and learn how to make your data AI-ready for successful outcomes.
Read more

Atlassian
Enhancing Performance of ScriptRunner for Jira Data Center - Script Fields in Atlassian Jira
Optimize Jira DataCenter performance with ScriptRunner – avoid bottlenecks and apply best practices for JQL queries and Script Fields.
Read more